掲示板 Forums - Interested in working with a renshuu API?
Top > renshuu.org > Developer corner
Page: 14 of 14
Getting the posts
Page: 14 of 14
Top > renshuu.org > Developer corner
Sorry for the false positive, my N4 grammar is still stuck at 99%. I made a mistake and looked at the N4 sentence stats which are at 100%.
Thanks for the request. Let me see if I can clarify something - you are actually looking to both add private sentences to the system, and then also add them into a list or schedule?
Hi マイコー, thanks for the reply, I'm requesting mainly the first part, that is adding existing sentences (the ones I already find via /v1/reibun/search) to a list or schedule by ID, like pressing + in the sentence lookup but in bulk, that alone would cover most of what I need!
I think exposing a heatmap endpoint could be doable - just the data that sits behind the current heatmap implementation.
I can also add "first learned", as that is stored, but while it exists in *a* form, getting quick and easy access to historical data (specifically, mastery level changes) would not be realistic.
If you, however, would prefer to be able to look up a term and get a list of each time it was quizzed, the vector, and whether you got it right or not, I could do that. It doesn't contain the "mastery went from a to b", but you would still have a "mastery went up or down" based on if it was correct or not.
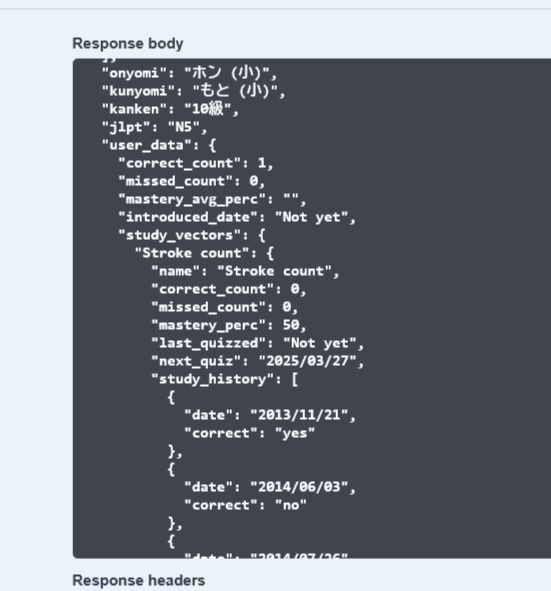
I think it would be reasonable to place first learned/quizzed in a "study_vectors" as well as the list of each time it was quizzed and was correct or not.
Anyway I'm waiting for this to be implemented. Could I help with anything?
アンドル - I can definitely get the sentences the same options as the other term types. Will report back when it is ready!
サロ - there is nothing that you (or anyone else) can do to help, but I do appreciate the offer!
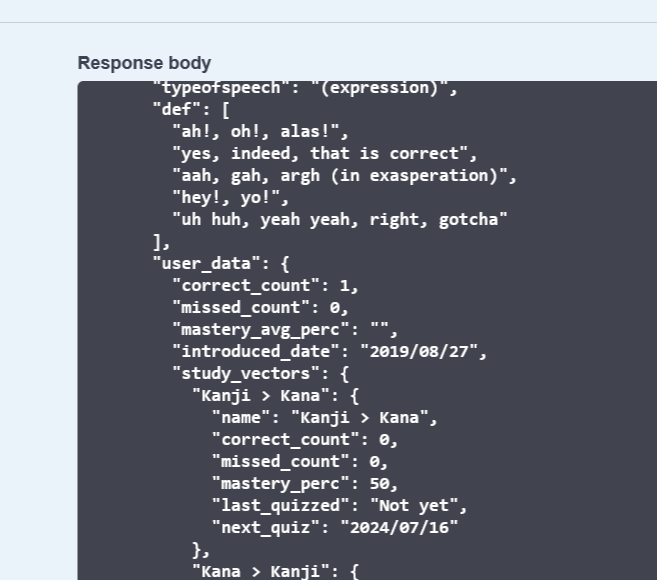
1. I do not think placing it under study_vectors would be ideal - it's putting a single data alongside all the other objects (vectors) of data. So, for now, I've just added "introduced_date" (first_studied)

As to the study history, that'll take a bit longer. It sits on a slower server, so I don't want to include it by default and slow down every user term lookup. It'll have to be an additional flag to enable it.
紫紺 - can you show me where it is showing 99% still? I do not see that number for your /profile endpoint.
マイコー, Thanks for this update!
Although, now that I look at it.. Does each vector stores the data when was the first time it was studied? Now that we have introduced_date I think it means that any first vector was studied on that day. Can we have the same but for each vector?
マイコー, Also for some reason I have one character ー 天. That says "Not yet". Which is probably a bug. Could it be fixed?
Each vector does not save first studied, at least, not in the same place. It would be part of the larger dataset of history per vector, but that would be hidden behind the flag due to a larger resource drain.
/heatmap endpoint is up for testing!
/reibun/{id} now exists with put/get/delete options, just like the other term types. Only minimal testing done, so let me know if you have any issues!

I'm sure I studied this kanji but it says introduced_date - not yet, why?
{
"kanjis": [
{
"id": "1997",
"kanji": "天",
"scount": "4",
"definition": "heavens, sky, imperial",
"onyomi": "テン (小)",
"kunyomi": "あま (小), あめ (高), そら (x)",
"kanken": "10級",
"jlpt": "N5",
"user_data": {
"correct_count": 15,
"missed_count": 0,
"mastery_avg_perc": "33",
"introduced_date": "Not yet",
"study_vectors": {
"Stroke count": {
"name": "Stroke count",
"correct_count": 1,
"missed_count": 0,
"mastery_perc": 0,
"last_quizzed": "2026/10/15",
"next_quiz": "2026/10/16"
},
"Onyomi": {
"name": "Onyomi",
"correct_count": 5,
"missed_count": 0,
"mastery_perc": 75,
"last_quizzed": "2026/10/15",
"next_quiz": "2026/11/20"
},
"Kunyomi": {
"name": "Kunyomi",
"correct_count": 0,
"missed_count": 0,
"mastery_perc": 0,
"last_quizzed": "Not yet",
"next_quiz": "Now"
},
"Radical": {
"name": "Radical",
"correct_count": 1,
"missed_count": 0,
"mastery_perc": 0,
"last_quizzed": "2026/10/15",
"next_quiz": "2026/10/16"
},
"Writing": {
"name": "Writing",
"correct_count": 2,
"missed_count": 0,
"mastery_perc": 0,
"last_quizzed": "2026/10/15",
"next_quiz": "2026/10/16"
},
"Definition": {
"name": "Definition",
"correct_count": 5,
"missed_count": 0,
"mastery_perc": 88,
"last_quizzed": "2026/10/15",
"next_quiz": "2026/12/16"
}
}
}
}
],
"result_count": 1,
"api_usage": {
"calls_today": "3",
"daily_allowance": 2000
}
}

It looks amazing! Thank you! Although I was thinking it to be in the /list/all/{termtype} sorry for not specifying this.. I don't really see how it would work for me in a individual lookups, since there can be thousands of words but we have only 2000 requests limit on a pro. Could you add it to /list/all/{termtype} with a flag? Otherwise I need to make thousands of requests to update the history :(
Each vector does not save first studied, at least, not in the same place. It would be part of the larger dataset of history per vector, but that would be hidden behind the flag due to a larger resource drain.
/heatmap endpoint is up for testing!
I'm a little bit confused with a heatmap.
1. I don't see a year in the data. What will happen on the next year? How will I be able to get historical data?
2. The "studied x%" response. First of all it is a string. The second things is that it is a %. I would like to have a number instead if possible. As for the "future date". "future_date" can be dropped since I can calculate which date will be tomorrow myself. "scheduled holiday" is fine tho.